Runpod uses usage-based pricing rather than fixed subscription tiers. Dedicated GPU Pods start at $0.27/hour, Serverless workers at $0.58/hour, and Clusters at $1.79/hour — all billed per second, with no contracts or minimum commitments.
Runpod costs between $0.27 and $9.98 per hour with usage-based pricing across its main offerings: Pods (dedicated GPU instances) from $0.27/hr, Serverless workers from $0.58/hr, Clusters from $1.79/hr, plus pay-per-request Public Endpoints.
There are no fixed subscription tiers here — you pay for the compute you actually use, billed by the second. Here's how each piece works.
Pods
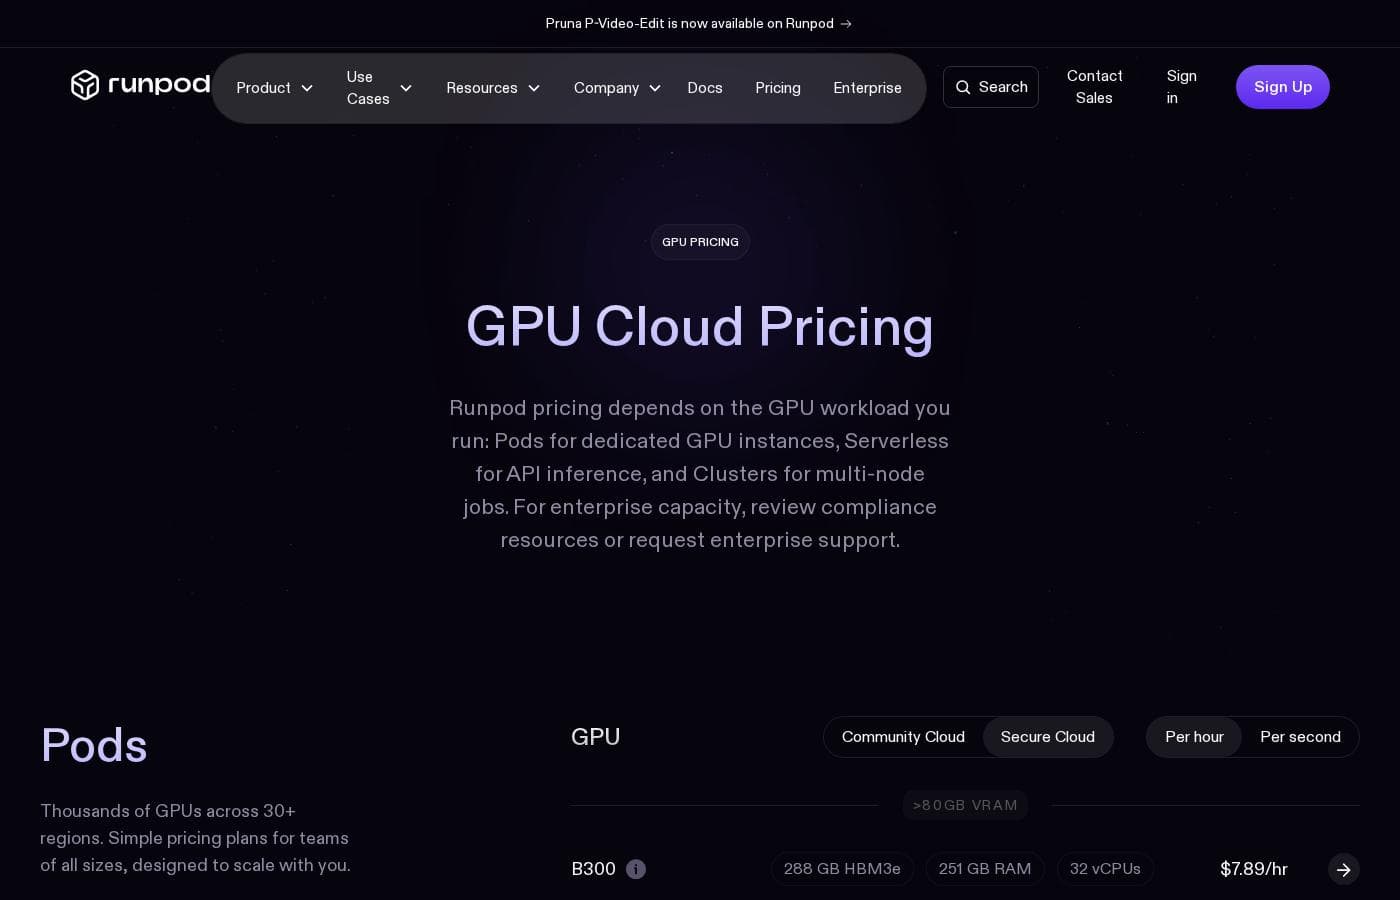
Price: From $0.27/hour (RTX A5000) up to $7.89/hour (B300), billed per second
Best For: Development, fine-tuning, and long-running jobs that need a dedicated GPU
Other Features:
- 20+ GPU types, including H100, A100, L40S, RTX 4090, and B300
- Choice of Community Cloud or Secure Cloud
- Deployed across 30+ global regions
- Each GPU has defined VRAM, RAM, and vCPUs
Pods are the pick if you want a machine that stays yours. Spin one up for an afternoon of experiments or keep it running for weeks. Budget builders should stick to cards like the A5000 or RTX 3090; save the H100s and B300s for heavy training.
Serverless
Price: From $0.58/hour per worker (small GPUs) up to $9.98/hour (B300)
Best For: API-based inference that scales with traffic
Other Features:
- Zero idle cost — endpoints cost nothing when not running
- Autoscales from 0 to thousands of workers
- Sub-200ms cold starts with FlashBoot
- Flex workers save 25% over other serverless providers
This is the option for production apps with unpredictable traffic. You only pay while a worker processes a request. If your workload comes in bursts, Serverless handles the scaling for you.
Clusters
Price: H200 SXM at $4.31/hour; A100 SXM at $1.79/hour; other GPUs quoted by sales
Best For: Multi-node distributed training and large-batch inference
Other Features:
- Scale up to 64 GPUs with no commitments
- Shared storage can be attached
- Launch multi-GPU clusters in minutes
- Reserved Clusters add SLA-backed uptime and discounts for large deployments
Clusters suit teams running serious distributed jobs. Training large models across many GPUs? Start here. Reserved Clusters offer 1–12+ month commitments at discounted rates, so talk to sales before locking in.
Storage
Price: From $0.05/GB/month (standard network storage over 1TB)
Best For: Persisting models, datasets, and checkpoints
Other Features:
- Container disk: $0.10/GB/month
- Volume disk: $0.10/GB/month running, $0.20/GB/month idle
- High-performance network storage: $0.14/GB/month
Storage is billed separately from compute, so factor it into your total. Idle volumes cost double, so delete what you're not using.
Public Endpoints
Price: Per request — for example, $0.005–$0.14 per image generation
Best For: Instant API access to pre-deployed models
Other Features:
- Audio, image, video, and language models
- Whisper V3 Large at $0.05 per 1,000 characters
- FLUX.1 Schnell at $0.0024 per megapixel
This is the simplest way to use Runpod. Pick a model, call the API, and pay per request. No GPU management required.
Runpod doesn't list a free trial or money-back guarantee on its pricing page, but on-demand compute carries no contracts or minimum commitments — you simply stop paying when you stop using it. Long-term reservations unlock extra discounts on active and flex workers if you can commit. Before scaling up, confirm whether Community Cloud or Secure Cloud pricing fits your compliance needs, since the two environments differ.